

Prepare Top Databricks Databricks-Certified-Data-Analyst-Associate Exam Study Guide Practice Questions Edition
Go to Databricks-Certified-Data-Analyst-Associate Questions - Try Databricks-Certified-Data-Analyst-Associate dumps pdf
NEW QUESTION # 40
The stakeholders.customers table has 15 columns and 3,000 rows of data. The following command is run: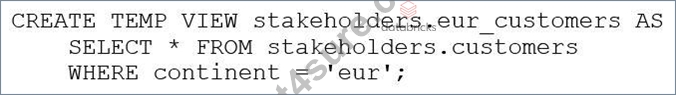
After running SELECT * FROM stakeholders.eur_customers, 15 rows are returned. After the command executes completely, the user logs out of Databricks.
After logging back in two days later, what is the status of the stakeholders.eur_customers view?
- A. The view is not available in the metastore, but the underlying data can be accessed with SELECT * FROM delta. `stakeholders.eur_customers`.
- B. The view remains available and SELECT * FROM stakeholders.eur_customers will execute correctly.
- C. The view has been dropped.
- D. The view has been converted into a table.
- E. The view remains available but attempting to SELECT from it results in an empty result set because data in views are automatically deleted after logging out.
Answer: C
Explanation:
The command you sent creates a TEMP VIEW, which is a type of view that is only visible and accessible to the session that created it. When the session ends or the user logs out, the TEMP VIEW is automatically dropped and cannot be queried anymore. Therefore, after logging back in two days later, the status of the stakeholders.eur_customers view is that it has been dropped and SELECT * FROM stakeholders.eur_customers will result in an error. The other options are not correct because:
A) The view does not remain available, as it is a TEMP VIEW that is dropped when the session ends or the user logs out.
C) The view is not available in the metastore, as it is a TEMP VIEW that is not registered in the metastore. The underlying data cannot be accessed with SELECT * FROM delta. stakeholders.eur_customers, as this is not a valid syntax for querying a Delta Lake table. The correct syntax would be SELECT * FROM delta.dbfs:/stakeholders/eur_customers, where the location path is enclosed in backticks. However, this would also result in an error, as the TEMP VIEW does not write any data to the file system and the location path does not exist.
D) The view does not remain available, as it is a TEMP VIEW that is dropped when the session ends or the user logs out. Data in views are not automatically deleted after logging out, as views do not store any data. They are only logical representations of queries on base tables or other views.
E) The view has not been converted into a table, as there is no automatic conversion between views and tables in Databricks. To create a table from a view, you need to use a CREATE TABLE AS statement or a similar command. Reference: CREATE VIEW | Databricks on AWS, Solved: How do temp views actually work? - Databricks - 20136, temp tables in Databricks - Databricks - 44012, Temporary View in Databricks - BIG DATA PROGRAMMERS, Solved: What is the difference between a Temporary View an ...
NEW QUESTION # 41
A data analyst has been asked to count the number of customers in each region and has written the following query: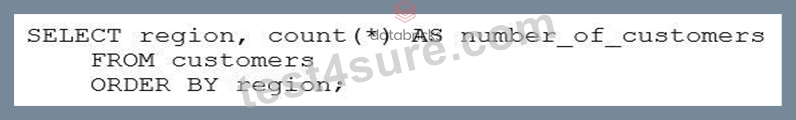
If there is a mistake in the query, which of the following describes the mistake?
- A. The query is missing a GROUP BY region clause.
- B. The query is selecting region but region should only occur in the ORDER BY clause.
- C. There are no mistakes in the query.
- D. The query is using ORDER BY. which is not allowed in an aggregation.
- E. The query is using count('). which will count all the customers in the customers table, no matter the region.
Answer: A
Explanation:
In the provided SQL query, the data analyst is trying to count the number of customers in each region. However, they made a mistake by not including the "GROUP BY" clause to group the results by region. Without this clause, the query will not return counts for each distinct region but rather an error or incorrect result. Reference: The need for a GROUP BY clause in such queries can be understood from Databricks SQL documentation: Databricks SQL.
I also noticed that you uploaded an image with your question. The image shows a snippet of an SQL query written in plain text on a white background. The query is attempting to select regions and count customers from a "customers" table and order the results by region. There's no visible syntax highlighting or any other color - it's monochromatic. The query is the same as the one in your question. I'm not sure why you included the image, but maybe you wanted to show me the exact format of your query. If so, you can also use code blocks to display formatted content such as SQL queries. For example, you can write:
SELECT region, count(*) AS number_of_customers
FROM customers
ORDER BY region;
This way, you can avoid uploading images and make your questions more clear and concise. I hope this helps.
NEW QUESTION # 42
A data analyst wants to create a Databricks SQL dashboard with multiple data visualizations and multiple counters. What must be completed before adding the data visualizations and counters to the dashboard?
- A. All data visualizations and counters must be created using Queries.
- B. A SQL warehouse (formerly known as SQL endpoint) must be turned on and selected.
- C. The dashboard owner must also be the owner of the queries, data visualizations, and counters.
- D. A markdown-based tile must be added to the top of the dashboard displaying the dashboard's name.
Answer: A
Explanation:
In Databricks SQL, when creating a dashboard that includes multiple data visualizations and counters, it is imperative that each visualization and counter is based on a query. The process involves the following steps:
Develop Queries:
For each desired visualization or counter, write a SQL query that retrieves the necessary data.
Create Visualizations and Counters:
After executing each query, utilize the results to create corresponding visualizations or counters. Databricks SQL offers a variety of visualization types to represent data effectively.
Assemble the Dashboard:
Add the created visualizations and counters to your dashboard, arranging them as needed to convey the desired insights.
By ensuring that all components of the dashboard are derived from queries, you maintain consistency, accuracy, and the ability to refresh data as needed. This approach also facilitates easier maintenance and updates to the dashboard elements.
NEW QUESTION # 43
In which of the following situations will the mean value and median value of variable be meaningfully different?
- A. When the variable contains no missing values
- B. When the variable contains no outliers
- C. When the variable contains a lot of extreme outliers
- D. When the variable is of the boolean type
- E. When the variable is of the categorical type
Answer: C
Explanation:
The mean value of a variable is the average of all the values in a data set, calculated by dividing the sum of the values by the number of values. The median value of a variable is the middle value of the ordered data set, or the average of the middle two values if the data set has an even number of values. The mean value is sensitive to outliers, which are values that are very different from the rest of the data. Outliers can skew the mean value and make it less representative of the central tendency of the data. The median value is more robust to outliers, as it only depends on the middle values of the data. Therefore, when the variable contains a lot of extreme outliers, the mean value and the median value will be meaningfully different, as the mean value will be pulled towards the outliers, while the median value will remain close to the majority of the data1. Reference: Difference Between Mean and Median in Statistics (With Example) - BYJU'S
NEW QUESTION # 44
Which of the following benefits of using Databricks SQL is provided by Data Explorer?
- A. It can be used to make visualizations that can be shared with stakeholders.
- B. It can be used to view metadata and data, as well as view/change permissions.
- C. It can be used to run UPDATE queries to update any tables in a database.
- D. It can be used to connect to third party Bl cools.
- E. It can be used to produce dashboards that allow data exploration.
Answer: B
Explanation:
Data Explorer is a user interface that allows you to discover and manage data, schemas, tables, models, and permissions in Databricks SQL. You can use Data Explorer to view schema details, preview sample data, and see table and model details and properties. Administrators can view and change owners, and admins and data object owners can grant and revoke permissions1. Reference: Discover and manage data using Data Explorer
NEW QUESTION # 45
A data analyst wants the following output:
customer_name number_of_orders
John Doe 388
Zhang San 234
Which statement will produce this output?
- A. SELECT customer_name, count(order_id) AS number_of_orders
FROM customers
JOIN orders
ON customers.customer_id = orders.customer_id
GROUP BY customer_name; - B. SELECT customerjiame, count(order_id)
FROM customers
JOIN orders
ON customers.customer_id = orders.customer_id GROUP BY customerjiame; - C. SELECT customer_name, count(order_id) number_of_orders
FROM customers
JOIN orders
ON customers.customer_id = orders.customer_id USE customer_name; - D. SELECT customerjiame, (order_id) number_of_orders
FROM customers
JOIN orders
ON customers.customer_id = orders.customer_id;
Answer: A
NEW QUESTION # 46
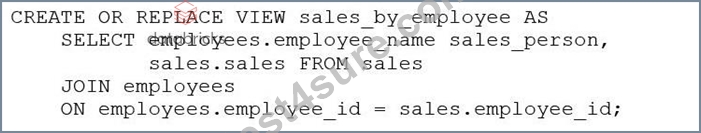
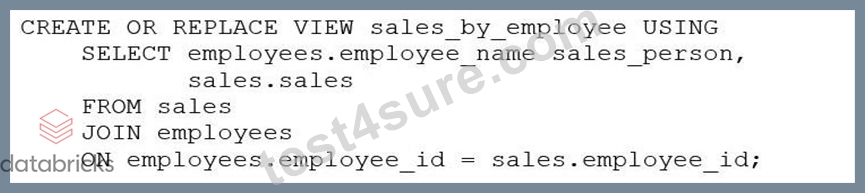
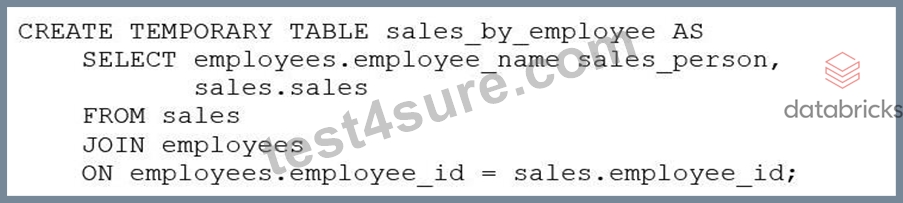
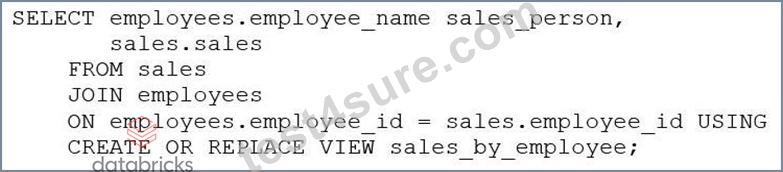
A business analyst has been asked to create a data entity/object called sales_by_employee. It should always stay up-to-date when new data are added to the sales table. The new entity should have the columns sales_person, which will be the name of the employee from the employees table, and sales, which will be all sales for that particular sales person. Both the sales table and the employees table have an employee_id column that is used to identify the sales person.
Which of the following code blocks will accomplish this task?
- A.
- B.
- C.
- D.
Answer: A
Explanation:
The SQL code provided in Option D is the correct way to create a view named sales_by_employee that will always stay up-to-date with the sales and employees tables. The code uses the CREATE OR REPLACE VIEW statement to define a new view that joins the sales and employees tables on the employee_id column. It selects the employee_name as sales_person and all sales for each employee, ensuring that the data entity/object is always up-to-date when new data are added to these tables.
NEW QUESTION # 47
A data analyst has created a user-defined function using the following line of code:
CREATE FUNCTION price(spend DOUBLE, units DOUBLE)
RETURNS DOUBLE
RETURN spend / units;
Which of the following code blocks can be used to apply this function to the customer_spend and customer_units columns of the table customer_summary to create column customer_price?
- A. SELECT price FROM customer_summary
- B. SELECT price(customer_spend, customer_units) AS customer_price FROM customer_summary
- C. SELECT PRICE customer_spend, customer_units AS customer_price FROM customer_summary
- D. SELECT double(price(customer_spend, customer_units)) AS customer_price FROM customer_summary
- E. SELECT function(price(customer_spend, customer_units)) AS customer_price FROM customer_summary
Answer: B
Explanation:
A user-defined function (UDF) is a function defined by a user, allowing custom logic to be reused in the user environment1. To apply a UDF to a table, the syntax is SELECT udf_name(column_name) AS alias FROM table_name2. Therefore, option E is the correct way to use the UDF price to create a new column customer_price based on the existing columns customer_spend and customer_units from the table customer_summary. Reference:
What are user-defined functions (UDFs)?
User-defined scalar functions - SQL
V
NEW QUESTION # 48
What is used as a compute resource for Databricks SQL?
- A. SQL warehouses
- B. Standard clusters
- C. Downstream BI tools integrated with Databricks SQL
- D. Single-node clusters
Answer: A
NEW QUESTION # 49
A data analyst has created a Query in Databricks SQL, and now they want to create two data visualizations from that Query and add both of those data visualizations to the same Databricks SQL Dashboard.
Which of the following steps will they need to take when creating and adding both data visualizations to the Databricks SQL Dashboard?
- A. They will need to alter the Query to return two separate sets of results.
- B. They will need to add two separate visualizations to the dashboard based on the same Query.
- C. They will need to copy the Query and create one data visualization per query.
- D. They will need to decide on a single data visualization to add to the dashboard.
- E. They will need to create two separate dashboards.
Answer: B
Explanation:
A data analyst can create multiple visualizations from the same query in Databricks SQL by clicking the + button next to the Results tab and selecting Visualization. Each visualization can have a different type, name, and configuration. To add a visualization to a dashboard, the data analyst can click the vertical ellipsis button beneath the visualization, select + Add to Dashboard, and choose an existing or new dashboard. The data analyst can repeat this process for each visualization they want to add to the same dashboard. Reference: Visualization in Databricks SQL, Visualize queries and create a dashboard in Databricks SQL
NEW QUESTION # 50
A data scientist has asked a data analyst to create histograms for every continuous variable in a data set. The data analyst needs to identify which columns are continuous in the data set.
What describes a continuous variable?
- A. A quantitative variable that can take on an uncountable set of values
- B. A quantitative variable that never stops changing
- C. A quantitative variable Chat can take on a finite or countably infinite set of values
- D. A categorical variable in which the number of categories continues to increase over time
Answer: A
Explanation:
A continuous variable is a type of quantitative variable that can assume an infinite number of values within a given range. This means that between any two possible values, there can be an infinite number of other values. For example, variables such as height, weight, and temperature are continuous because they can be measured to any level of precision, and there are no gaps between possible values. This is in contrast to discrete variables, which can only take on specific, distinct values (e.g., the number of children in a family). Understanding the nature of continuous variables is crucial for data analysts, especially when selecting appropriate statistical methods and visualizations, such as histograms, to accurately represent and analyze the data.
NEW QUESTION # 51
A data organization has a team of engineers developing data pipelines following the medallion architecture using Delta Live Tables. While the data analysis team working on a project is using gold-layer tables from these pipelines, they need to perform some additional processing of these tables prior to performing their analysis.
Which of the following terms is used to describe this type of work?
- A. Data enhancement
- B. Data blending
- C. Last-mile
- D. Data testing
- E. Last-mile ETL
Answer: E
Explanation:
Last-mile ETL is the term used to describe the additional processing of data that is done by data analysts or data scientists after the data has been ingested, transformed, and stored in the lakehouse by data engineers. Last-mile ETL typically involves tasks such as data cleansing, data enrichment, data aggregation, data filtering, or data sampling that are specific to the analysis or machine learning use case. Last-mile ETL can be done using Databricks SQL, Databricks notebooks, or Databricks Machine Learning. Reference: Databricks - Last-mile ETL, Databricks - Data Analysis with Databricks SQL
NEW QUESTION # 52
A data analyst has been asked to configure an alert for a query that returns the income in the accounts_receivable table for a date range. The date range is configurable using a Date query parameter.
The Alert does not work.
Which of the following describes why the Alert does not work?
- A. The wrong query parameter is being used. Alerts only work with Date and Time query parameters.
- B. The wrong query parameter is being used. Alerts only work with drogdown list query parameters, not dates.
- C. Queries that return results based on dates cannot be used with Alerts.
- D. Alerts don't work with queries that access tables.
- E. Queries that use query parameters cannot be used with Alerts.
Answer: E
Explanation:
According to the Databricks documentation1, queries that use query parameters cannot be used with Alerts. This is because Alerts do not support user input or dynamic values. Alerts leverage queries with parameters using the default value specified in the SQL editor for each parameter. Therefore, if the query uses a Date query parameter, the alert will always use the same date range as the default value, regardless of the actual date. This may cause the alert to not work as expected, or to not trigger at all. Reference:
Databricks SQL alerts: This is the official documentation for Databricks SQL alerts, where you can find information about how to create, configure, and monitor alerts, as well as the limitations and best practices for using alerts.
NEW QUESTION # 53
Which of the following approaches can be used to connect Databricks to Fivetran for data ingestion?
- A. Use Delta Live Tables to establish a cluster for Fivetran to interact with
- B. Use Partner Connect's automated workflow to establish a SQL warehouse (formerly known as a SQL endpoint) for Fivetran to interact with
- C. Use Partner Connect's automated workflow to establish a cluster for Fivetran to interact with
- D. Use Workflows to establish a cluster for Fivetran to interact with
- E. Use Workflows to establish a SQL warehouse (formerly known as a SQL endpoint) for Fivetran to interact with
Answer: C
Explanation:
Partner Connect is a feature that allows you to easily connect your Databricks workspace to Fivetran and other ingestion partners using an automated workflow. You can select a SQL warehouse or a cluster as the destination for your data replication, and the connection details are sent to Fivetran. You can then choose from over 200 data sources that Fivetran supports and start ingesting data into Delta Lake. Reference: Connect to Fivetran using Partner Connect, Use Databricks with Fivetran
NEW QUESTION # 54
A data analyst has created a Query in Databricks SQL, and now they want to create two data visualizations from that Query and add both of those data visualizations to the same Databricks SQL Dashboard.
Which of the following steps will they need to take when creating and adding both data visualizations to the Databricks SQL Dashboard?
- A. They will need to alter the Query to return two separate sets of results.
- B. They will need to add two separate visualizations to the dashboard based on the same Query.
- C. They will need to copy the Query and create one data visualization per query.
- D. They will need to decide on a single data visualization to add to the dashboard.
- E. They will need to create two separate dashboards.
Answer: B
Explanation:
A data analyst can create multiple visualizations from the same query in Databricks SQL by clicking the + button next to the Results tab and selecting Visualization. Each visualization can have a different type, name, and configuration. To add a visualization to a dashboard, the data analyst can click the vertical ellipsis button beneath the visualization, select + Add to Dashboard, and choose an existing or new dashboard. The data analyst can repeat this process for each visualization they want to add to the same dashboard. Reference: Visualization in Databricks SQL, Visualize queries and create a dashboard in Databricks SQL
NEW QUESTION # 55
A data analyst runs the following command:
INSERT INTO stakeholders.suppliers TABLE stakeholders.new_suppliers;
What is the result of running this command?
- A. The suppliers table now contains the data from the new suppliers table, and the new suppliers table now contains the data from the suppliers table.
- B. The suppliers table now contains both the data it had before the command was run and the data from the new suppliers table, including any duplicate data.
- C. The suppliers table now contains both the data it had before the command was run and the data from the new suppliers table, and any duplicate data is deleted.
- D. The command fails because it is written incorrectly.
- E. The suppliers table now contains only the data from the new suppliers table.
Answer: D
Explanation:
The command INSERT INTO stakeholders.suppliers TABLE stakeholders.new_suppliers is not a valid syntax for inserting data into a table in Databricks SQL. According to the documentation12, the correct syntax for inserting data into a table is either:
INSERT { OVERWRITE | INTO } [ TABLE ] table_name [ PARTITION clause ] [ ( column_name [, ...] ) | BY NAME ] query INSERT INTO [ TABLE ] table_name REPLACE WHERE predicate query The command in the question is missing the OVERWRITE or INTO keyword, and the query part that specifies the source of the data to be inserted. The TABLE keyword is optional and can be omitted. The PARTITION clause and the column list are also optional and depend on the table schema and the data source. Therefore, the command in the question will fail with a syntax error.
Reference:
INSERT | Databricks on AWS
INSERT - Azure Databricks - Databricks SQL | Microsoft Learn
NEW QUESTION # 56
A data engineering team has created a Structured Streaming pipeline that processes data in micro-batches and populates gold-level tables. The microbatches are triggered every minute.
A data analyst has created a dashboard based on this gold-level dat
a. The project stakeholders want to see the results in the dashboard updated within one minute or less of new data becoming available within the gold-level tables.
Which of the following cautions should the data analyst share prior to setting up the dashboard to complete this task?
- A. The required compute resources could be costly
- B. The gold-level tables are not appropriately clean for business reporting
- C. The streaming cluster is not fault tolerant
- D. The dashboard cannot be refreshed that quickly
- E. The streaming data is not an appropriate data source for a dashboard
Answer: A
Explanation:
A Structured Streaming pipeline that processes data in micro-batches and populates gold-level tables every minute requires a high level of compute resources to handle the frequent data ingestion, processing, and writing. This could result in a significant cost for the organization, especially if the data volume and velocity are large. Therefore, the data analyst should share this caution with the project stakeholders before setting up the dashboard and evaluate the trade-offs between the desired refresh rate and the available budget. The other options are not valid cautions because:
B . The gold-level tables are assumed to be appropriately clean for business reporting, as they are the final output of the data engineering pipeline. If the data quality is not satisfactory, the issue should be addressed at the source or silver level, not at the gold level.
C . The streaming data is an appropriate data source for a dashboard, as it can provide near real-time insights and analytics for the business users. Structured Streaming supports various sources and sinks for streaming data, including Delta Lake, which can enable both batch and streaming queries on the same data.
D . The streaming cluster is fault tolerant, as Structured Streaming provides end-to-end exactly-once fault-tolerance guarantees through checkpointing and write-ahead logs. If a query fails, it can be restarted from the last checkpoint and resume processing.
E . The dashboard can be refreshed within one minute or less of new data becoming available in the gold-level tables, as Structured Streaming can trigger micro-batches as fast as possible (every few seconds) and update the results incrementally. However, this may not be necessary or optimal for the business use case, as it could cause frequent changes in the dashboard and consume more resources. Reference: Streaming on Databricks, Monitoring Structured Streaming queries on Databricks, A look at the new Structured Streaming UI in Apache Spark 3.0, Run your first Structured Streaming workload
NEW QUESTION # 57
A data analysis team is working with the table_bronze SQL table as a source for one of its most complex projects. A stakeholder of the project notices that some of the downstream data is duplicative. The analysis team identifies table_bronze as the source of the duplication.
Which of the following queries can be used to deduplicate the data from table_bronze and write it to a new table table_silver?
A)
CREATE TABLE table_silver AS
SELECT DISTINCT *
FROM table_bronze;
B)
CREATE TABLE table_silver AS
INSERT *
FROM table_bronze;
C)
CREATE TABLE table_silver AS
MERGE DEDUPLICATE *
FROM table_bronze;
D)
INSERT INTO TABLE table_silver
SELECT * FROM table_bronze;
E)
INSERT OVERWRITE TABLE table_silver
SELECT * FROM table_bronze;
- A. Option A
- B. Option D
- C. Option B
- D. Option E
- E. Option C
Answer: A
Explanation:
Option A uses the SELECT DISTINCT statement to remove duplicate rows from the table_bronze and create a new table table_silver with the deduplicated data. This is the correct way to deduplicate data using Spark SQL12. Option B simply inserts all the rows from table_bronze into table_silver, without removing any duplicates. Option C is not a valid syntax for Spark SQL, as there is no MERGE DEDUPLICATE statement. Option D appends all the rows from table_bronze into table_silver, without removing any duplicates. Option E overwrites the existing data in table_silver with the data from table_bronze, without removing any duplicates. Reference: Delete Duplicate using SPARK SQL, Spark SQL - How to Remove Duplicate Rows
NEW QUESTION # 58
A data analyst is attempting to drop a table my_table. The analyst wants to delete all table metadata and data.
They run the following command:
DROP TABLE IF EXISTS my_table;
While the object no longer appears when they run SHOW TABLES, the data files still exist.
Which of the following describes why the data files still exist and the metadata files were deleted?
- A. The table was external
- B. The table's data was larger than 10 GB
- C. The table was managed
- D. The table did not have a location
- E. The table's data was smaller than 10 GB
Answer: A
Explanation:
An external table is a table that is defined in the metastore, but its data is stored outside of the Databricks environment, such as in S3, ADLS, or GCS. When an external table is dropped, only the metadata is deleted from the metastore, but the data files are not affected. This is different from a managed table, which is a table whose data is stored in the Databricks environment, and whose data files are deleted when the table is dropped. To delete the data files of an external table, the analyst needs to specify the PURGE option in the DROP TABLE command, or manually delete the files from the storage system. Reference: DROP TABLE, Drop Delta table features, Best practices for dropping a managed Delta Lake table
NEW QUESTION # 59
Delta Lake stores table data as a series of data files, but it also stores a lot of other information.
Which of the following is stored alongside data files when using Delta Lake?
- A. None of these
- B. Data summary visualizations
- C. Table metadata, data summary visualizations, and owner account information
- D. Table metadata
- E. Owner account information
Answer: D
Explanation:
Delta Lake stores table data as a series of data files in a specified location, but it also stores table metadata in a transaction log. The table metadata includes the schema, partitioning information, table properties, and other configuration details. The table metadata is stored alongside the data files and is updated atomically with every write operation. The table metadata can be accessed using the DESCRIBE DETAIL command or the DeltaTable class in Scala, Python, or Java. The table metadata can also be enriched with custom tags or user-defined commit messages using the TBLPROPERTIES or userMetadata options. Reference:
Enrich Delta Lake tables with custom metadata
Delta Lake Table metadata - Stack Overflow
Metadata - The Internals of Delta Lake
NEW QUESTION # 60
In which of the following situations should a data analyst use higher-order functions?
- A. When built-in functions are taking too long to perform tasks
- B. When custom logic needs to be applied to simple, unnested data
- C. When custom logic needs to be applied at scale to array data objects
- D. When built-in functions need to run through the Catalyst Optimizer
- E. When custom logic needs to be converted to Python-native code
Answer: C
Explanation:
Higher-order functions are a simple extension to SQL to manipulate nested data such as arrays. A higher-order function takes an array, implements how the array is processed, and what the result of the computation will be. It delegates to a lambda function how to process each item in the array. This allows you to define functions that manipulate arrays in SQL, without having to unpack and repack them, use UDFs, or rely on limited built-in functions. Higher-order functions provide a performance benefit over user defined functions. Reference: Higher-order functions | Databricks on AWS, Working with Nested Data Using Higher Order Functions in SQL on Databricks | Databricks Blog, Higher-order functions - Azure Databricks | Microsoft Learn, Optimization recommendations on Databricks | Databricks on AWS
NEW QUESTION # 61
Which location can be used to determine the owner of a managed table?
- A. Review the Owner field in the schema page using Data Explorer
- B. Review the Owner field in the table page using Catalog Explorer
- C. Review the Owner field in the table page using the SQL Editor
- D. Review the Owner field in the database page using Data Explorer
Answer: B
Explanation:
In Databricks, to determine the owner of a managed table, you can utilize the Catalog Explorer feature. The steps are as follows:
Access Catalog Explorer:
In your Databricks workspace, click on the Catalog icon in the sidebar to open Catalog Explorer.
Navigate to the Table:
Within Catalog Explorer, browse through the catalog and schema to locate the specific managed table whose ownership you wish to verify.
View Table Details:
Click on the table name to open its details page.
Identify the Owner:
On the table's details page, review the Owner field, which displays the principal (user, service principal, or group) that owns the table.
This method provides a straightforward way to ascertain the ownership of managed tables within the Databricks environment. Understanding table ownership is essential for managing permissions and ensuring proper access control.
NEW QUESTION # 62
......
Free Data Analyst Databricks-Certified-Data-Analyst-Associate Exam Question: https://freecert.test4sure.com/Databricks-Certified-Data-Analyst-Associate-exam-materials.html